

- Regionalisation is the process of delineating regions: choosing criteria, measuring them over space and locating the boundaries where one region ends and another begins.
- It is a purposeful exercise, not a neutral one. The same space yields different regions for different aims.
- To develop arid land, only the arid areas form the region.
- To relieve congestion, the most congested and polluted areas form a “congested region”.
- To cut poverty and unemployment, a depressed region is delineated.
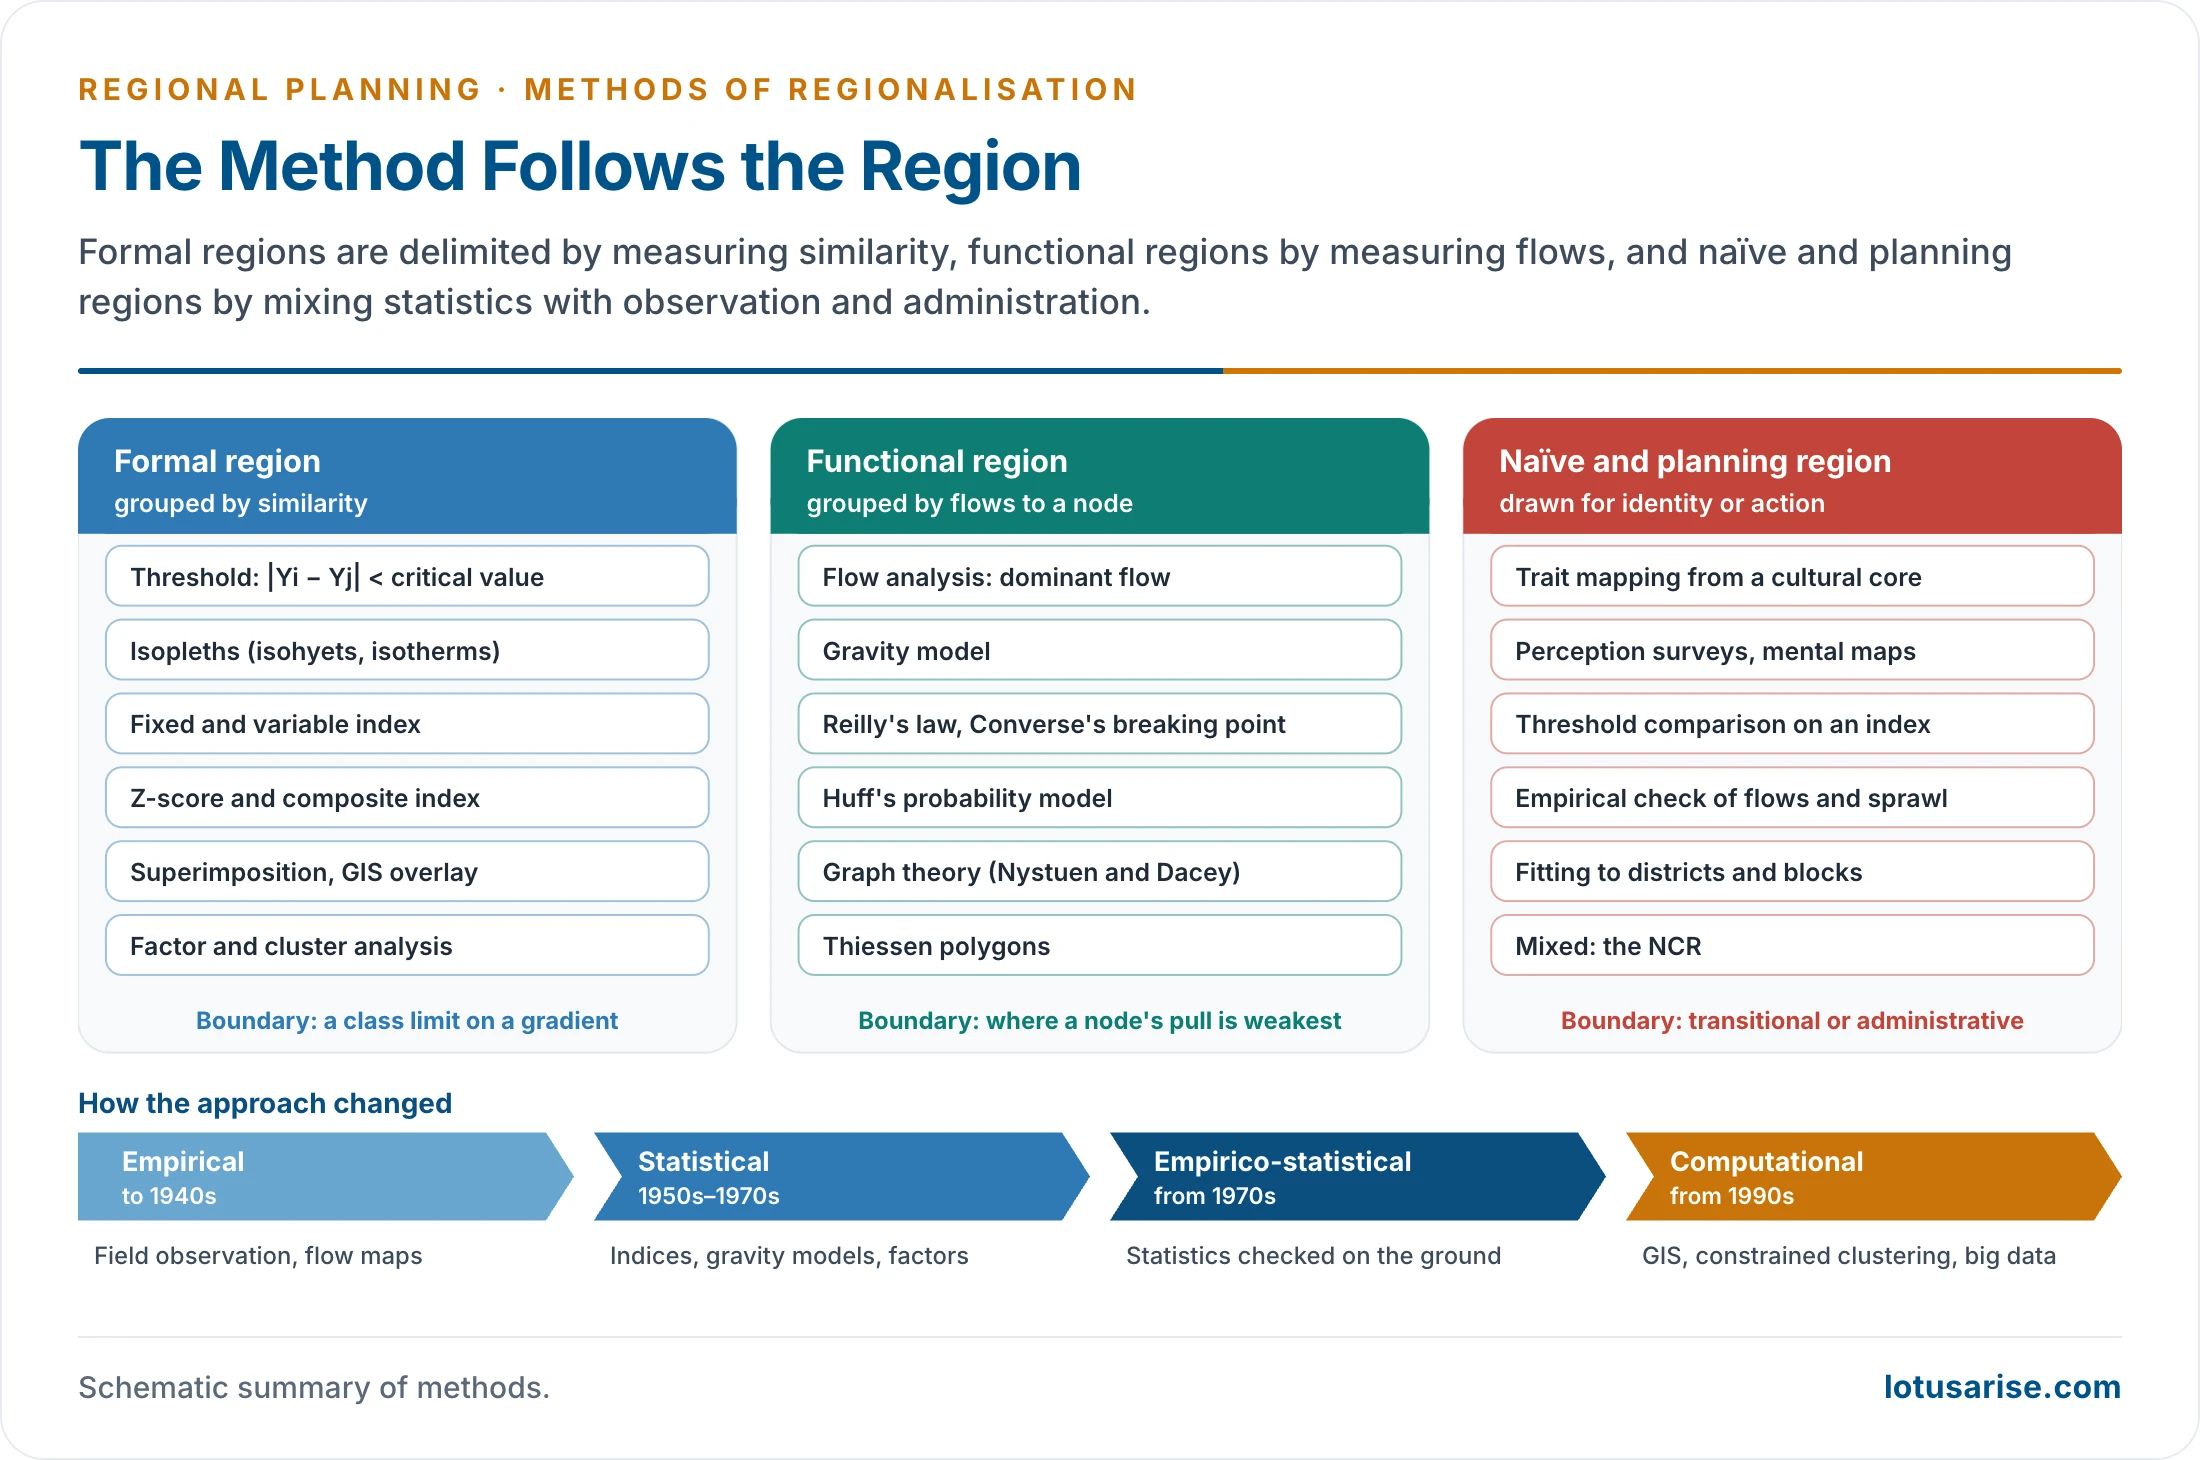
- The method follows the type of region: formal regions are delimited by similarity, functional regions by flows to a node, and perceptual or naïve regions by mixed empirical and statistical means.
- Methods have moved from field observation to statistics and models, and now to GIS and computational clustering, but every boundary remains a judgement about a gradient.
Regionalisation: Meaning, Steps and Criteria

Region and Regionalisation
| Basis | Region | Regionalisation |
|---|---|---|
| Nature | Product, outcome | Process, method |
| What it is | A bounded unit with defined characteristics | The exercise of delimiting and mapping such units |
| Key question | What is this area? | How and where is the boundary drawn? |
| Purpose | Unit of analysis or planning | Creating units for analysis or planning |
| Example | Thar Desert, NCR, BIMARU States | The method used to delimit them |
- David Grigg (1965) showed that regionalisation is a form of classification of places, bound by the same logical rules: a clear purpose, explicit criteria, and classes that are exhaustive and mutually exclusive.
- A region is marked by a degree of formal, functional or perceptual homogeneity; regionalisation reduces the complexity of an area to simple, understandable units.
- Groenman saw regionalisation as the differentiation of political measures in space. There is no universally acceptable method of doing it.
- Arbitrary delimitation invites ridicule. George H. T. Kimble (1951) mocked colleagues trying to put boundaries that do not exist around areas that do not matter. The defence is purpose: a boundary is valid for the problem it serves.
- Regionalisation takes different forms depending on:
- the purpose of delineation: developing arid land, reducing poverty, managing water, planning urban growth;
- the criteria used: land use, employment and activity rates, migration, rainfall, language, per capita income;
- the availability of data for the chosen units.
- If a physical region were also an administrative region, all tasks of regional planning would be easier. This rarely happens, so regionalisation always involves compromise.
- All regions, in one way or another, reflect the level of development of their area. Regionalisation changes as development priorities change.
- Planning means looking ahead and chalking out future courses of action: a preparatory, systematic activity that settles when, how and by whom a job will be done, and balances needs against available human and physical resources. A plan well made is said to be half done.
- Regionalisation serves planning. A planning region is the segment of territory over which economic decisions apply, planning here meaning decisions taken and carried out to attain economic development.
- The nation is the planning region for national plans, the State for State plans, and the district or block for micro-level plans, because these units have data and machinery.
- Regional delineation is therefore the first step of any regional plan: it fixes the operational area within which surveys are made and development is envisaged.
Steps in Regionalisation
- Define the purpose: the problem the region must serve.
- Choose criteria and indicators: variables that bear on many others in the area, such as population density, income or rainfall.
- Choose the base unit: village, block, district or grid cell, usually the unit for which data exist.
- Survey and measure: reconnaissance by more than one observer often gives non-coinciding boundaries; statistics replace impressions with measured values.
- Apply a technique: threshold, index, overlay, clustering or flow analysis.
- Generalise and draw boundaries where the largest number of criteria or interactions coincide.
- Validate and revise: test the region against field reality and update it as conditions change.
Criteria and Indicators
- A criterion is the principle on which places are grouped (aridity, backwardness, nodality); an indicator is the measurable variable that expresses it (rainfall, literacy, commuting share).
| Criterion group | Indicators | Typical use in India |
|---|---|---|
| Physical | Relief, geology, soil type, rainfall (isohyets), temperature (isotherms), climate (Köppen’s classes), vegetation, slope, drainage basin | Physiographic and agro-climatic regions, watersheds, drought-prone areas |
| Demographic | Density, growth rate, sex ratio, migration, urbanisation | Population regions, urban and rural planning |
| Economic | Per capita income, occupational structure, industrial employment, number of industries, rate of industrialisation, crop type, cropping intensity, unemployment | Industrial and agricultural regions, backward areas |
| Social and human development | Literacy, female literacy, infant mortality, nutrition, SC/ST share, poverty, multidimensional poverty | Composite development indices, aspirational districts |
| Infrastructural | Road density, electrification, bank branches, health and school facilities | Backward area identification, service-centre planning |
| Functional (flow) | Commuting, shopping trips, commodity flows, bus routes, newspaper circulation, telephone and data traffic | City regions, market areas, metropolitan regions |
| Cultural | Language, religion, ethnicity, political affiliation, customs, dialect, dress, food, festivals; these give fuzzy boundaries | Cultural and linguistic regions |
| Environmental | Forest cover, erosion, groundwater stage, ecological fragility | Eco-sensitive zones, hill and desert programmes |
- Good indicators are relevant to the purpose, measurable at the chosen unit, available for all units and dates, not redundant with one another, and comparable across space.
- A good regionalisation produces regions that are:
- aware of the regional problems and opportunities being addressed;
- viable units for planning and administrative action;
- internally cohesive and geographically contiguous;
- endowed with resources enough for satisfactory production, exchange and consumption;
- organised around at least one node or growth point, for functional and planning regions;
- supported by reliable data.
- For a planning region, these criteria are applied together, balancing homogeneity, nodality and administrative convergence, as set out in the types of regions.
Evolution of Approaches
| Approach | Period | Method | Typical tool | Limitation |
|---|---|---|---|---|
| Empirical | To the Second World War | Observation and judgement in the field | Flow mapping, cartographic tradition | Subjective; no precise boundary |
| Statistical | Quantitative revolution, 1950s–1970s | Measurement and models | Index methods, gravity models, Thiessen polygons, factor analysis | Static distance; ignores behaviour |
| Empirico-statistical | From the 1970s | Statistics checked against observed behaviour | Mixed criteria, surveys, GIS | Data-intensive and complex |
| Computational | From the 1990s | Spatial clustering with contiguity, big data | GIS overlay, constrained clustering, mobile and satellite data | Opaque algorithms; data privacy |
- Early regional work was, as V. V. Pokshishevsky remarked, fond of pictorial characterisation rather than scientific explanation; O. E. Baker’s Cotton Belt and Corn Belt of the USA are classic empirical regions.
- After the Second World War interest grew with planning tasks, and economists and community organisers joined geographers.
- The critical revolution in geography stressed that people, not particles, make regions, so purely mechanical methods do not last; flexibility returned through the empirico-statistical approach.
- Methods are also grouped as qualitative and quantitative:
- Qualitative (empirical): relative intensity comparison, flow analysis, trait mapping, the skyline method of superimposing service limits, and R. L. Singh’s method for the city region.
- Quantitative: index and composite methods, factor and cluster analysis, Reilly’s law, Converse’s breaking point, Stouffer’s intervening opportunities, Huff’s probability model, graph theory and the proximal (Thiessen) method.
Delimiting Formal (Homogeneous) Regions
- Delineation of formal regions groups local units that are alike on clearly defined criteria and differ significantly from units outside.
- Boundaries can be fairly precise where one criterion dominates: the 18°C mean temperature of the coldest month bounds Köppen’s tropical climates; administrative lines bound political regions.
- Variables commonly used: land use, demographic characteristics, transport infrastructure, social services and utilities, and socio-economic structure.
Relative Intensity: The Threshold Principle
- Let i and j be two segments of space with values Yi and Yj of an indicator, such as per capita income.
- The difference Yi − Yj measures how unlike they are.
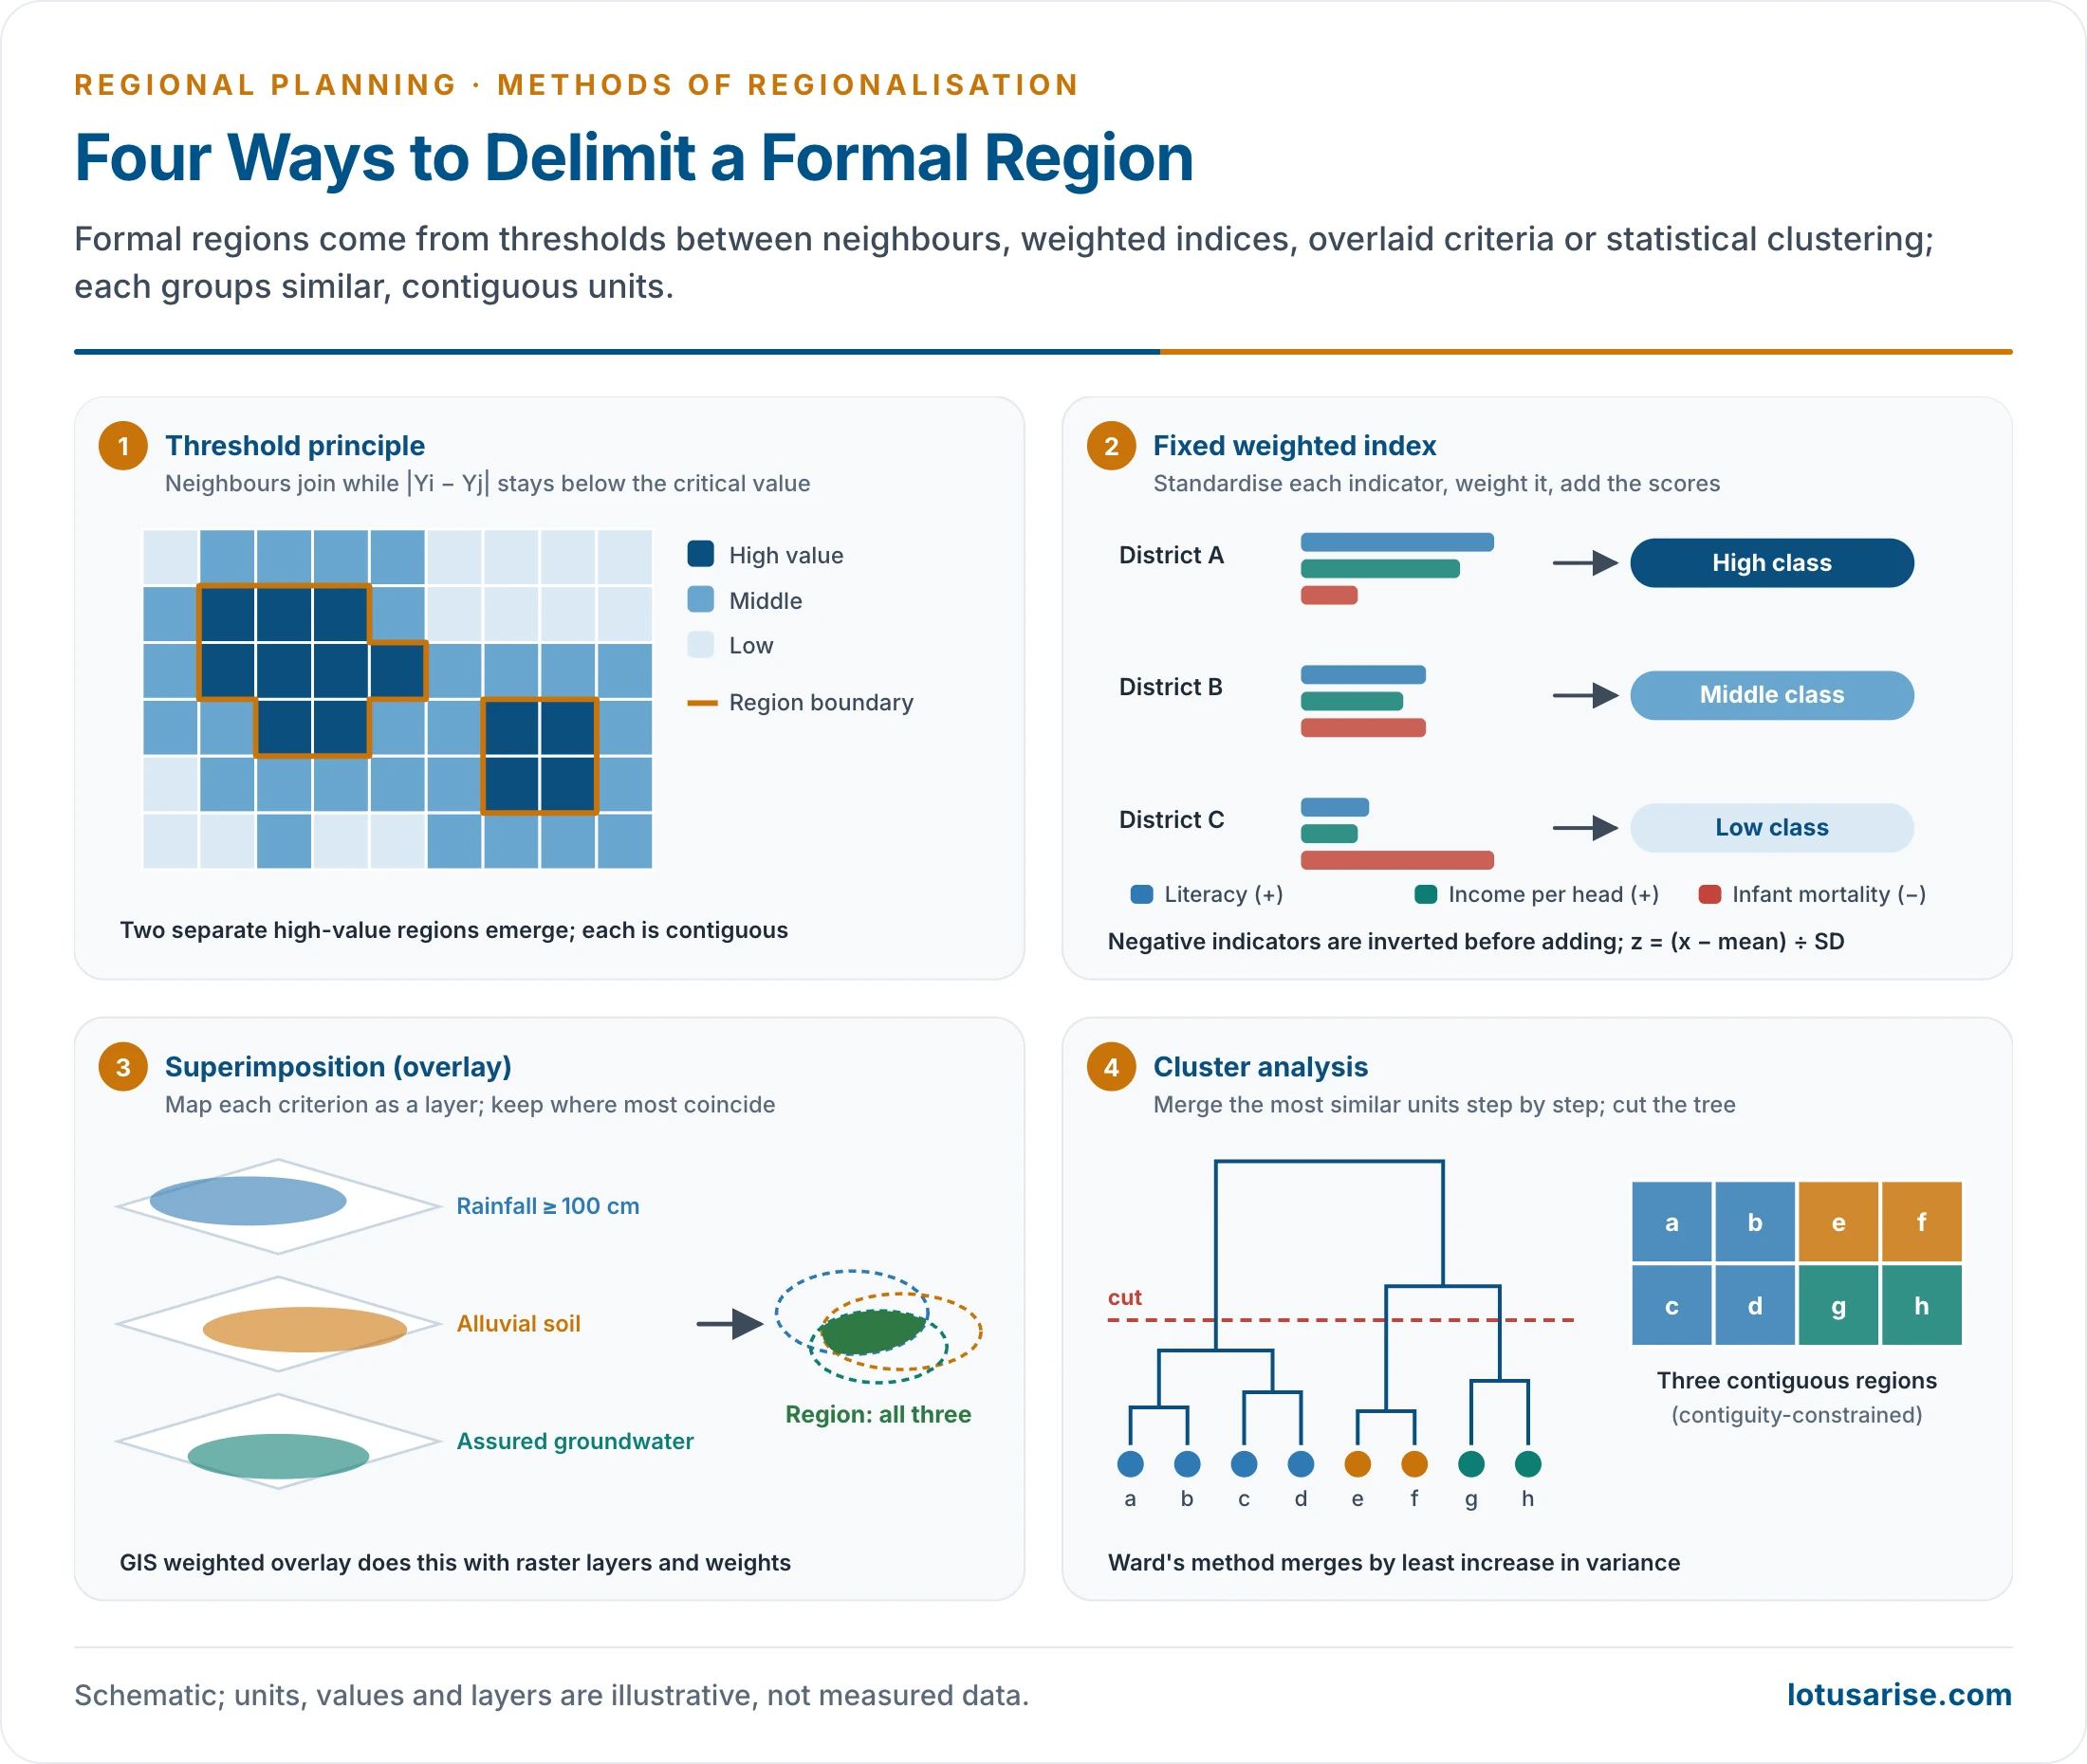
- The geographer fixes a threshold (critical value). If |Yi − Yj| is below it, i and j are homogeneous and belong to one region; if above, they fall in different regions.
- Applied unit by unit across a map, this relative intensity analysis grows regions outward from similar cores.
- It is the most accepted method for delimiting naïve regions such as backward areas on a single indicator: per capita income, literacy or a human development index.
- Single-criterion mapping uses the same logic with isopleths: isohyets for rainfall regions, isotherms for temperature regions, isochrones for travel time.
Weighted Index Methods
- When several criteria are used, they must be combined, and each must be given a weight. Three methods follow.
Fixed Index Method
- A set of indices common to all units is chosen, such as per capita income, unemployment and rate of industrialisation. Each is given an arbitrary but uniform weight.
- A single weighted mean is computed for each unit, and contiguous units with similar scores are grouped so as to minimise variance within each group.
- Jacques Boudeville outlined this as a weightage index method. The aim is often to isolate the problem region, the area of economic malaise, from a map of unemployment and income.
- Illustration: per capita income may get a weight of 3, unemployment 2 and infrastructure 1. Districts scoring 1–3 then form one region, 4–6 another and 7–10 a third: backward, intermediate and developed.
- Advantage: simple, comparable and transparent. Limit: arbitrary weights apply everywhere, even where relative importance varies by region.
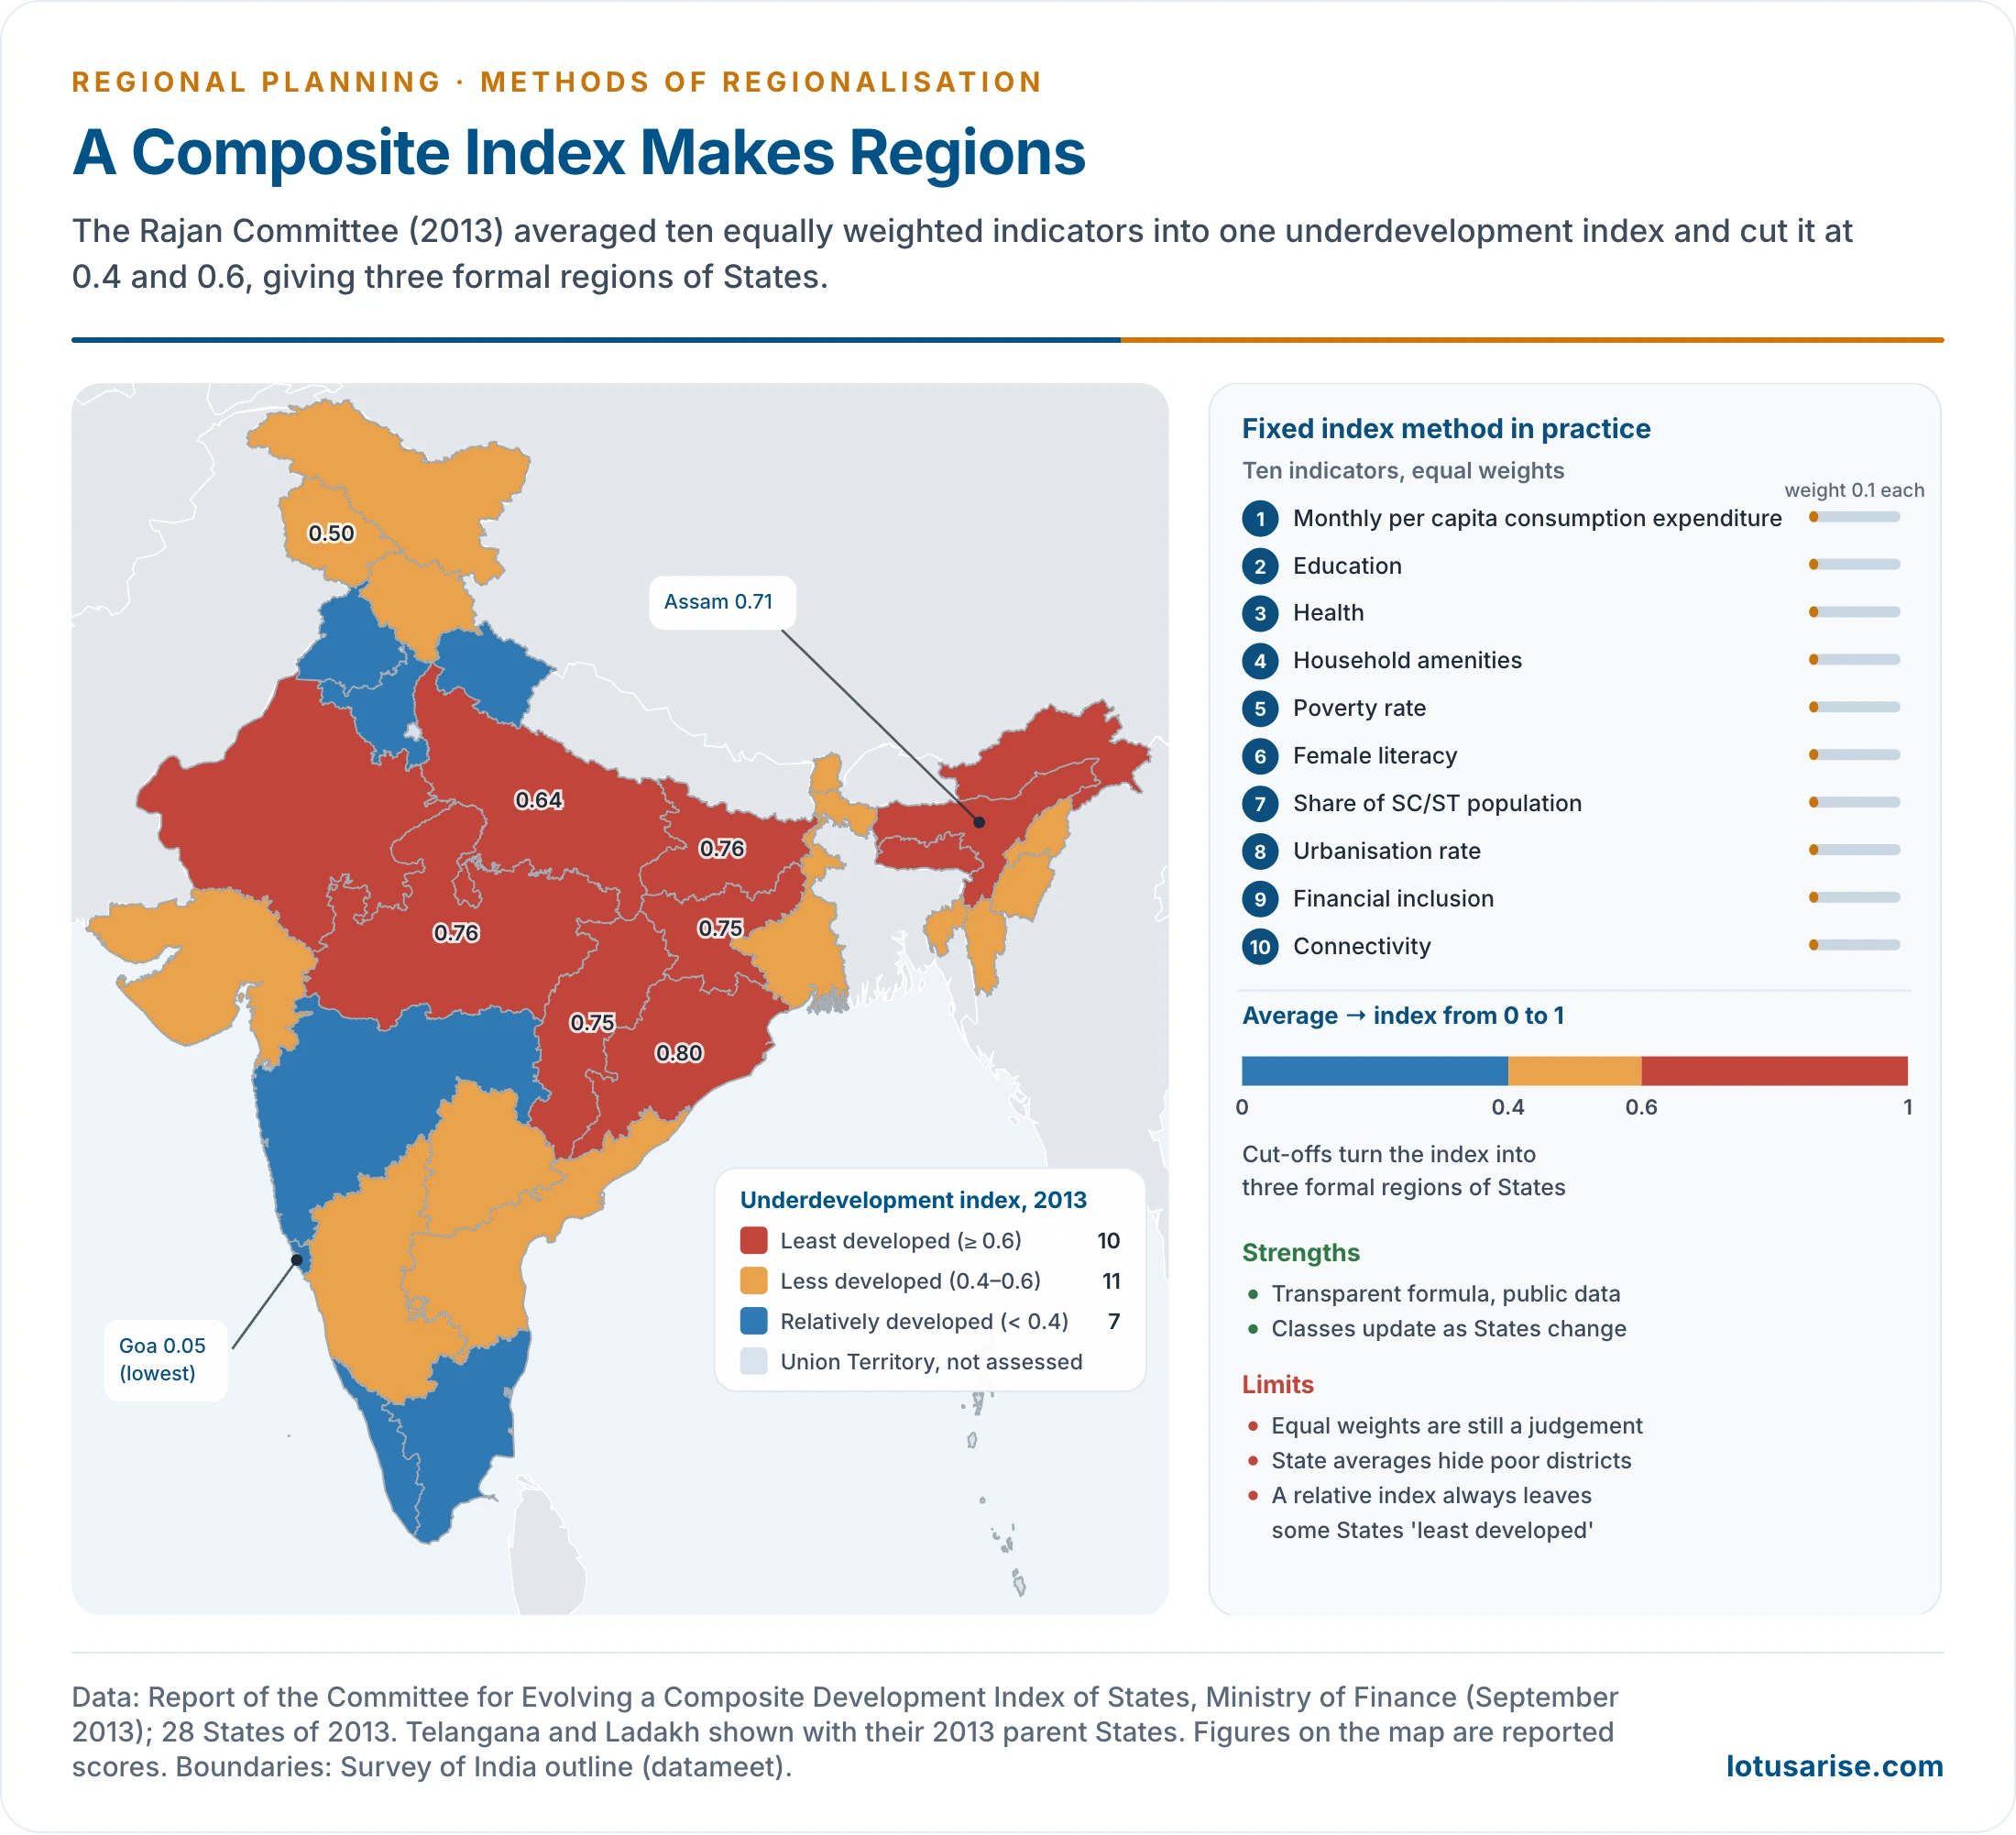
- India’s Rajan Committee (2013) is a clear example:
- The Committee for Evolving a Composite Development Index of States built an underdevelopment index from ten equally weighted sub-components: monthly per capita consumption, education, health, household amenities, poverty rate, female literacy, SC/ST share, urbanisation, financial inclusion and connectivity.
- States scoring 0.6 and above were “least developed” (10 States, led by Odisha at 0.80 and Bihar and Madhya Pradesh at 0.76), 0.4–0.6 “less developed” (11), and below 0.4 “relatively developed” (7, with Goa lowest at 0.05).
- Human development indices work the same way: health, education and income are combined into one score, and cut-offs give high, medium and low regions.
Variable Index Method
- Weights vary from region to region according to the value or volume of each activity there, so that each region’s specialisation stands out.
- If region A is a wheat region and region B a coal region, the wheat index carries the largest weight in A and the coal index in B.
- It works when the criteria are comparable. Where they are not, as with literacy and steel output, the cluster method is needed.
- Indian studies of levels of development by Ashok Mitra, Joseph E. Schwartzberg and M. N. Pal combined district indicators through weighting and composite ranking, mapping interrelated variables by superimposition. Composite ranking is used when variables are too many and weakly correlated.
| Feature | Fixed index | Variable index | Cluster or superimposition |
|---|---|---|---|
| Weights | Same for all units | Differ by region’s specialisation | No common weights; co-occurrence counts |
| Best when | Units are broadly comparable | Regions specialise in different activities | Variables are incompatible |
| Example | Backward-district index | Wheat region versus coal region | Land-use potential from rainfall, soil and water maps |
| Weakness | Arbitrary weights applied everywhere | Breaks down with incompatible variables | Boundary depends on how many layers must coincide |
Standardisation and Composite Indices
- Indicators come in different units, so they are first standardised:
- Z-score: z = (x − mean) ÷ standard deviation. Each unit is placed in standard deviations above or below the average; the z-scores of all indicators are summed or averaged into a composite score.
- Min–max (range) scaling: (x − minimum) ÷ (maximum − minimum), giving 0 to 1 or 0 to 100. NITI Aayog’s SDG India Index rescales each indicator to 0–100 this way and classes States as Aspirant, Performer, Front Runner and Achiever.
- Ranking: units are ranked on each indicator and the ranks summed, useful when data are rough.
- Direction must be aligned: high literacy is good but high infant mortality is bad, so one is inverted before combining.
- Illustration: if district literacy averages 70% with a standard deviation of 8, a district at 86% scores z = +2 and one at 62% scores z = −1. Adding such scores across literacy, income and health puts every district on one scale, whatever the original units.
- Weights may be equal (as in the Rajan index), set by experts, or derived statistically from principal components, which give more weight to indicators that carry more of the common variation.
- The composite score is then cut by thresholds (fixed values, quartiles or natural breaks) into classes, and contiguous units of one class form a region.
Superimposition (Overlay) Method
- Each criterion is mapped as a thematic layer: rainfall, soil, crops, groundwater. The layers are superimposed, and the area where all or most criteria coincide is the region.
- Plot India’s rainfall map, lay the soil map over it and then the water-availability map: the area with high rainfall, good soil and assured water stands out as a region of high land-use potential.
- The outermost line within which favourable conditions persist forms the boundary. Its weakness is that this line depends on how many criteria must coincide, a subjective choice.
- GIS weighted overlay has made the method precise: raster layers are reclassified, weighted and summed, as in land-suitability, watershed-priority and hazard-zonation mapping.
- Remote sensing extends formal regionalisation to the pixel: supervised classification of satellite images groups pixels with similar spectral signatures into land-use and land-cover regions, which are then generalised into mapped regions.
- Indian example: the Planning Commission’s agro-climatic zones (1989) were drawn by superimposing physiography, soils, rainfall and temperature, and water resources, then fitting the result to district boundaries for planning.
- Clustering is also used in planning itself: grouping villages into clusters large enough to share a secondary school, health centre and service centre, both by map overlay and by a composite index. The Integrated Rural Development Programme was carried out this way.
- Clusters strengthen lateral links and weaken growing vertical links in the settlement system. They give greater viability and threshold, and more bargaining power in the exchange of goods and services.
Multivariate Methods: Factor and Cluster Analysis
- Factor analysis and principal components reduce many intercorrelated indicators to a few underlying factors, and group areas by their factor scores.
- Margaret Jarman Hagood (1943) used principal components on 1939–40 census data to group the States of the USA into internally homogeneous, contiguous regions, an early multivariate regionalisation.
- Studies of “economic health” regions isolate factors such as industrial change, industrial structure, population change and social structure from dozens of criteria.
- Cluster analysis groups units step by step by similarity:
- Hierarchical clustering, such as Ward’s method (Joe H. Ward, 1963), merges the two most similar units or groups at each step, giving a dendrogram; cutting it at a chosen level gives the regions.
- Ordinary clustering ignores location, so regions may be scattered. Contiguity-constrained methods, such as SKATER (2006) and max-p regions (2012), force each region to be one connected piece.
- These methods are objective once the variables are chosen, but the choice of variables, the measure of similarity and the number of clusters remain judgements.
Delimiting Functional (Nodal) Regions
- Delineation of functional regions groups units that are interdependent with a centre. The concern is flows to a node, not uniformity.
- Each flow weakens with distance from the main centre and strengthens towards a rival centre. The boundary of a centre’s sphere lies where its flow is at a minimum, where places begin to orient elsewhere.
- Two basic approaches:
- Flow analysis, based on actual observation of what people do;
- Gravitational analysis, based on theoretical estimates of what people might do.
Flow Analysis
- The core node is identified, and primary data show how far its flows reach and in what intensity.
- Procedure:
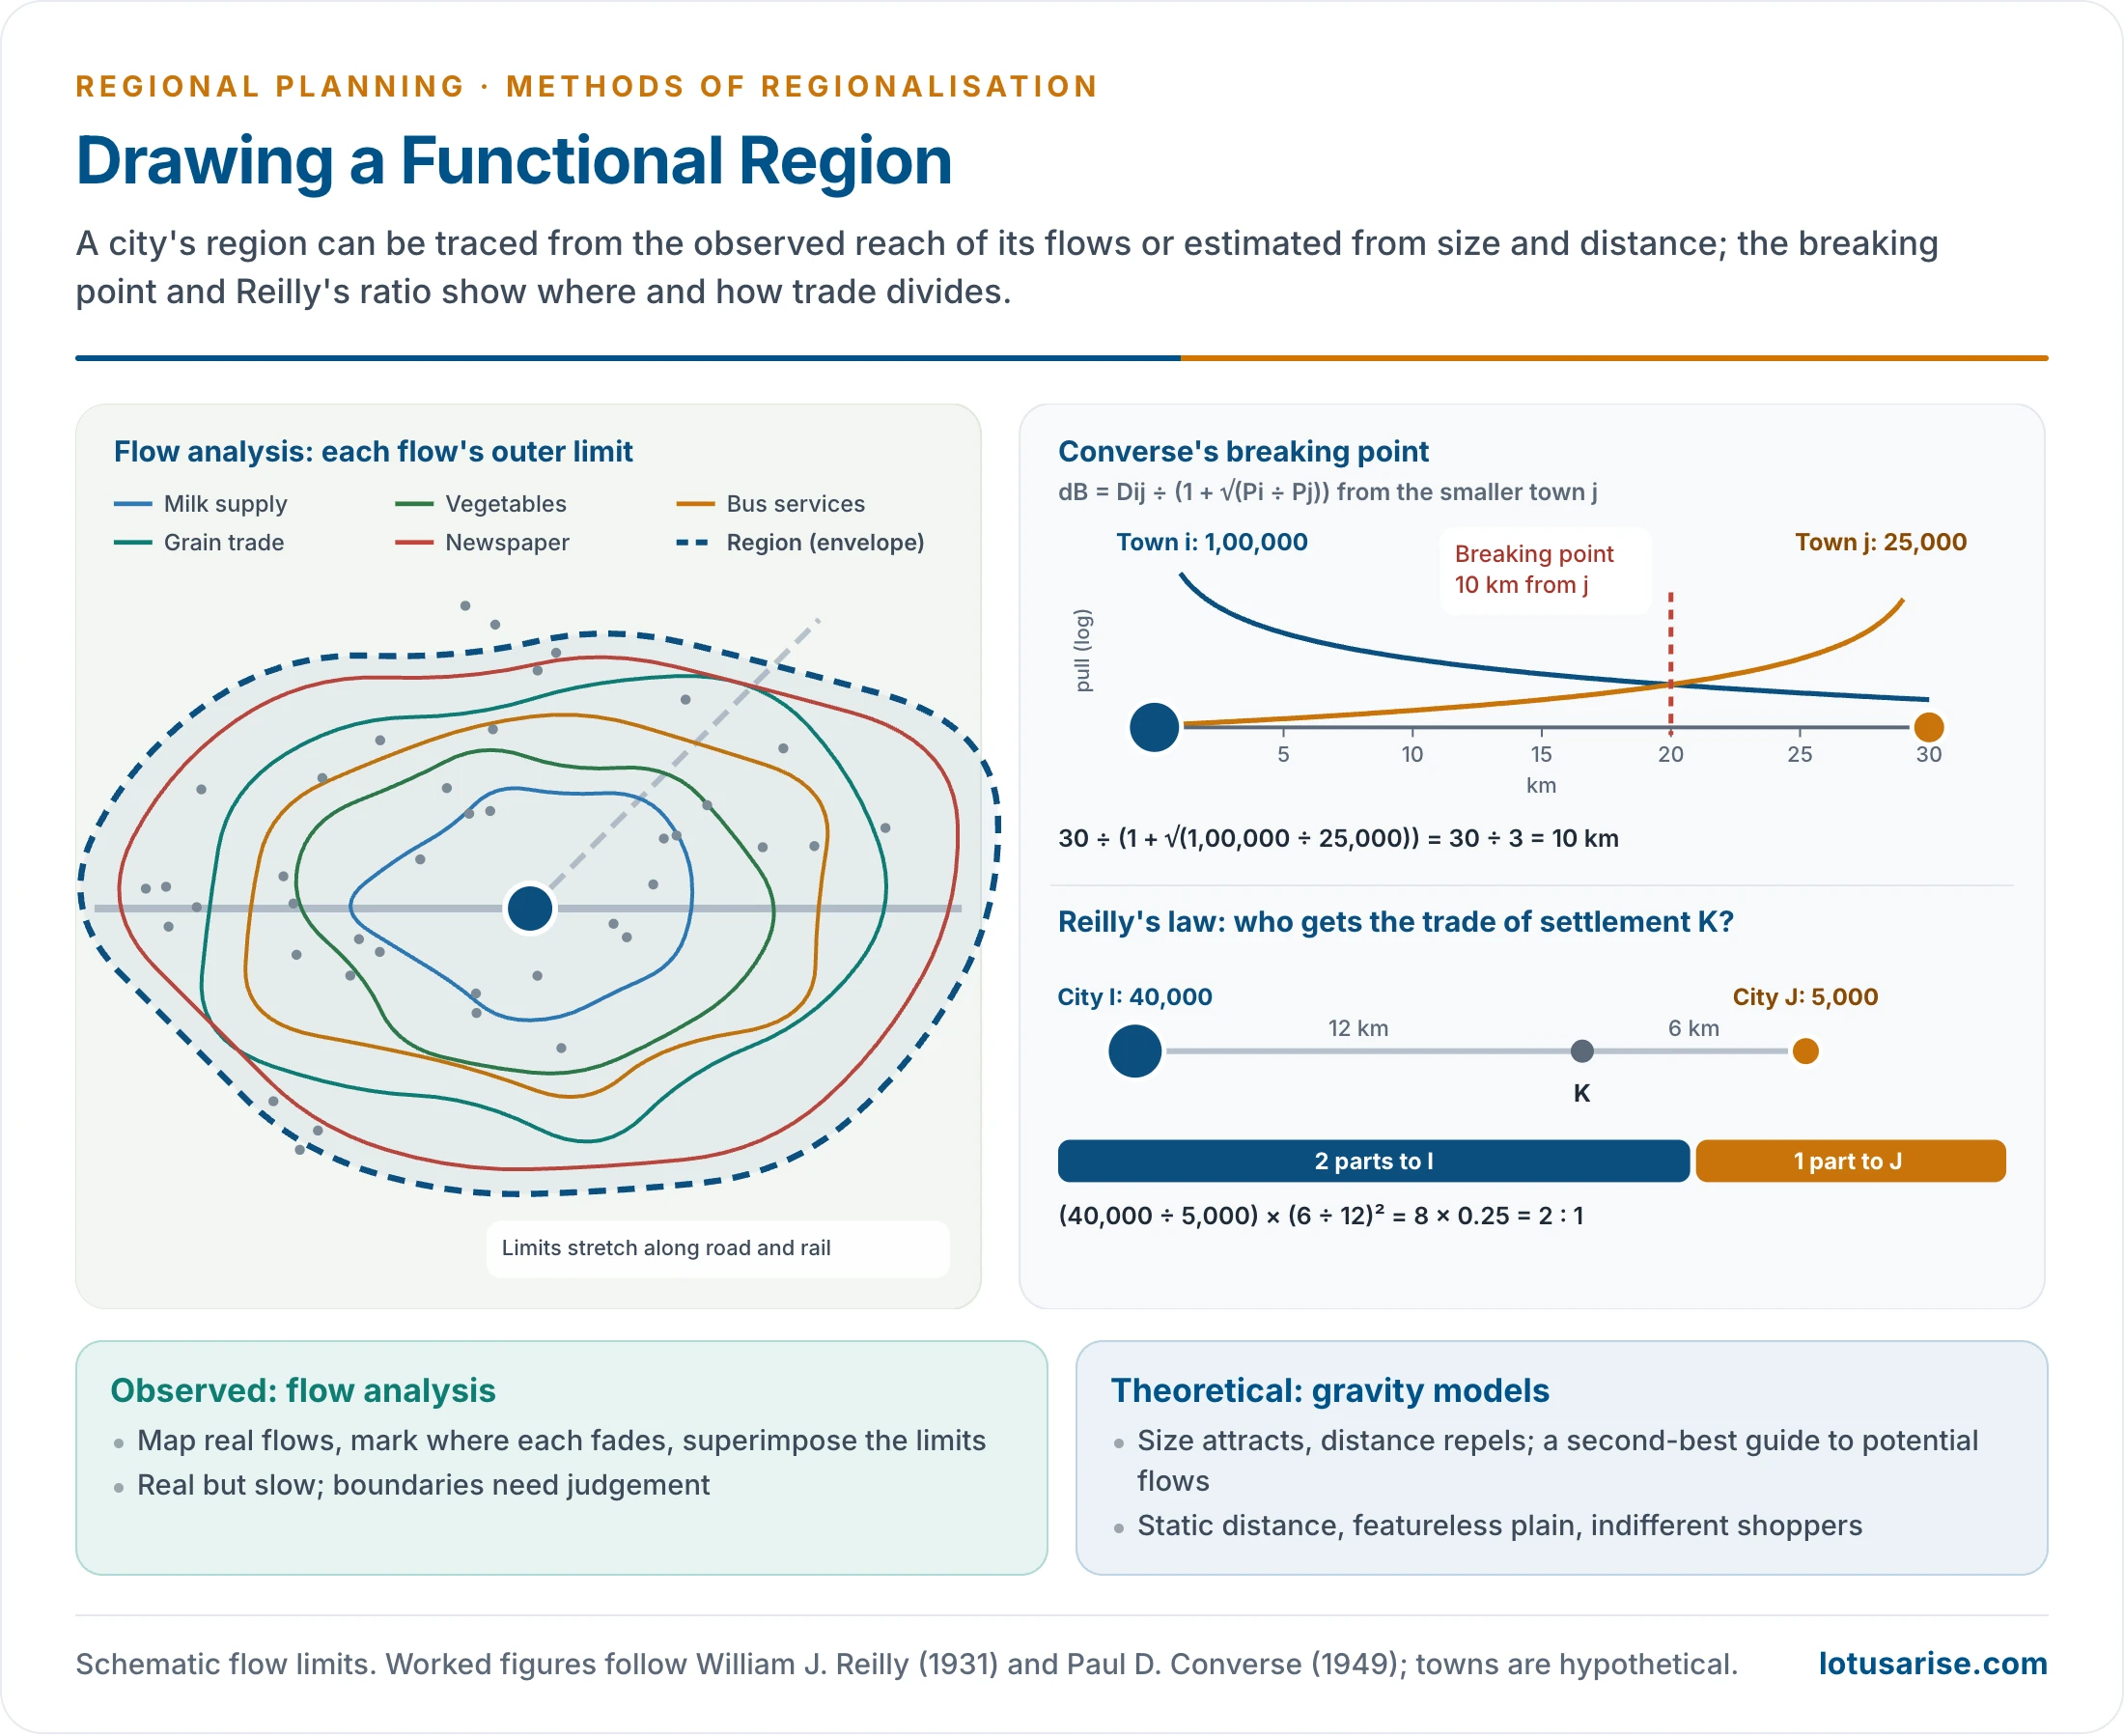
- Map each flow from the centre, by direction and volume, to surrounding places.
- Plot the intensity gradient along each route; where it drops sharply, or where a rival centre’s flow becomes larger, mark a cut-off point.
- Join the cut-off points for each flow, then superimpose the lines; the zone where most of them fall is the tentative boundary of the functional region.
- Flows differ in range: milk supply may reach about 50 km and daily newspaper delivery about 150 km. The outermost overlapping lines mark the limit of the sphere, which projects along main corridors and retracts at physical or competitive barriers.
- Flows may be economic (cargo, passengers), purpose-based (shopping, commuting), social (students, patients), political (government spending) or informational (newspapers, calls).
| Flow | What it captures | Data source |
|---|---|---|
| Commuting | Journey-to-work catchment | Census place of work and residence, travel surveys |
| Commodity | Supply links between city and hinterland | Origin–destination surveys, mandi arrivals, rail and GST e-way data |
| Migration | Labour catchment | Census and survey migration tables |
| Trade area | Retail and wholesale hinterland | Delivery records, shopper surveys |
| Information | Newspaper circulation, telephone and data traffic | Circulation audits, telecom data |
| Services | Students, patients, government spending | School, hospital and treasury records |
- Dominant-flow rule: each unit is assigned to the centre to which its largest flow goes. Threshold rule: a unit joins a centre’s region only if its flow exceeds a share.
- Metropolitan areas in the United States add an outlying county where at least 25% of its workers commute to the central counties.
- Indian example: R. L. Singh’s study of Banaras (1955) delimited the city’s umland by mapping vegetable and milk supply, grain trade, bus services, newspaper circulation and administrative reach, then superimposing them. Similar studies followed: U. Singh on Allahabad (1961) and on the KAVAL towns (Kanpur, Allahabad, Varanasi, Agra, Lucknow; 1962).
- Strength: it reflects real linkages. Limitations: it is data-hungry and slow, and gives irregular, judgement-based boundaries. The city region is partly a mental construct, hard to delimit by purely quantitative means.
Gravity Model, Breaking Point and Probability Models
- The gravity model estimates the potential interaction between centres: it rises with their size and falls with a power of the distance between them, Iij = k × Pi × Pj ÷ dij^b. It is a second-best to observed flows, useful where flow data are missing.
- Reilly’s law of retail gravitation (William J. Reilly, 1931): two cities attract trade from an intermediate place in direct proportion to their populations and in inverse proportion to the square of their distances from it.
- Mki ÷ Mkj = (Pi ÷ Pj) × (dkj ÷ dki)², where M is the trade drawn from intermediate town k, P population and d distance.
- Settlement K lies 12 km from city I (population 40,000) and 6 km from city J (5,000). The ratio of trade to I and J = (40,000 ÷ 5,000) × (6 ÷ 12)² = 8 × 0.25 = 2 : 1. The larger city wins despite being farther.
- Converse’s breaking point (Paul D. Converse, 1949) locates the boundary itself: dB = Dij ÷ (1 + √(Pi ÷ Pj)), measured from the smaller town j. Two towns 30 km apart with populations of 1,00,000 and 25,000 split their trade 10 km from the smaller one. Joining such points around a town gives its trade area polygon. The line lies nearer the smaller centre, gives a well-defined cut-off of influence, and is widely used in developed countries.
- Softer boundaries: David L. Huff (1963) makes the trade area a probability surface, and Samuel A. Stouffer (1940) counts intervening opportunities instead of distance alone.
- Limitations: masses and distances are hard to measure, distance is static and straight-line, and the plain is assumed featureless.
- Real Indian spheres of urban influence bend along rail and road lines and around rival centres, far from the model’s neat breaking points.
Graph Theory and Flow Matrices
- John D. Nystuen and Michael F. Dacey (1961) used graph theory on long-distance telephone calls between cities of Washington State. Each city’s largest outward flow pointed to its dominant city; the resulting tree of flows gave the nodal regions and the rank order of cities.
- Brian J. L. Berry (1966) factor-analysed India’s commodity flows by rail between 36 trade blocks, grouping destinations and origins with similar flow patterns into functional economic regions of the Indian space economy.
- Today mobile-phone, transaction and GPS data allow functional regions to be drawn from daily movement in near real time.
Thiessen Polygon (Proximal) Method
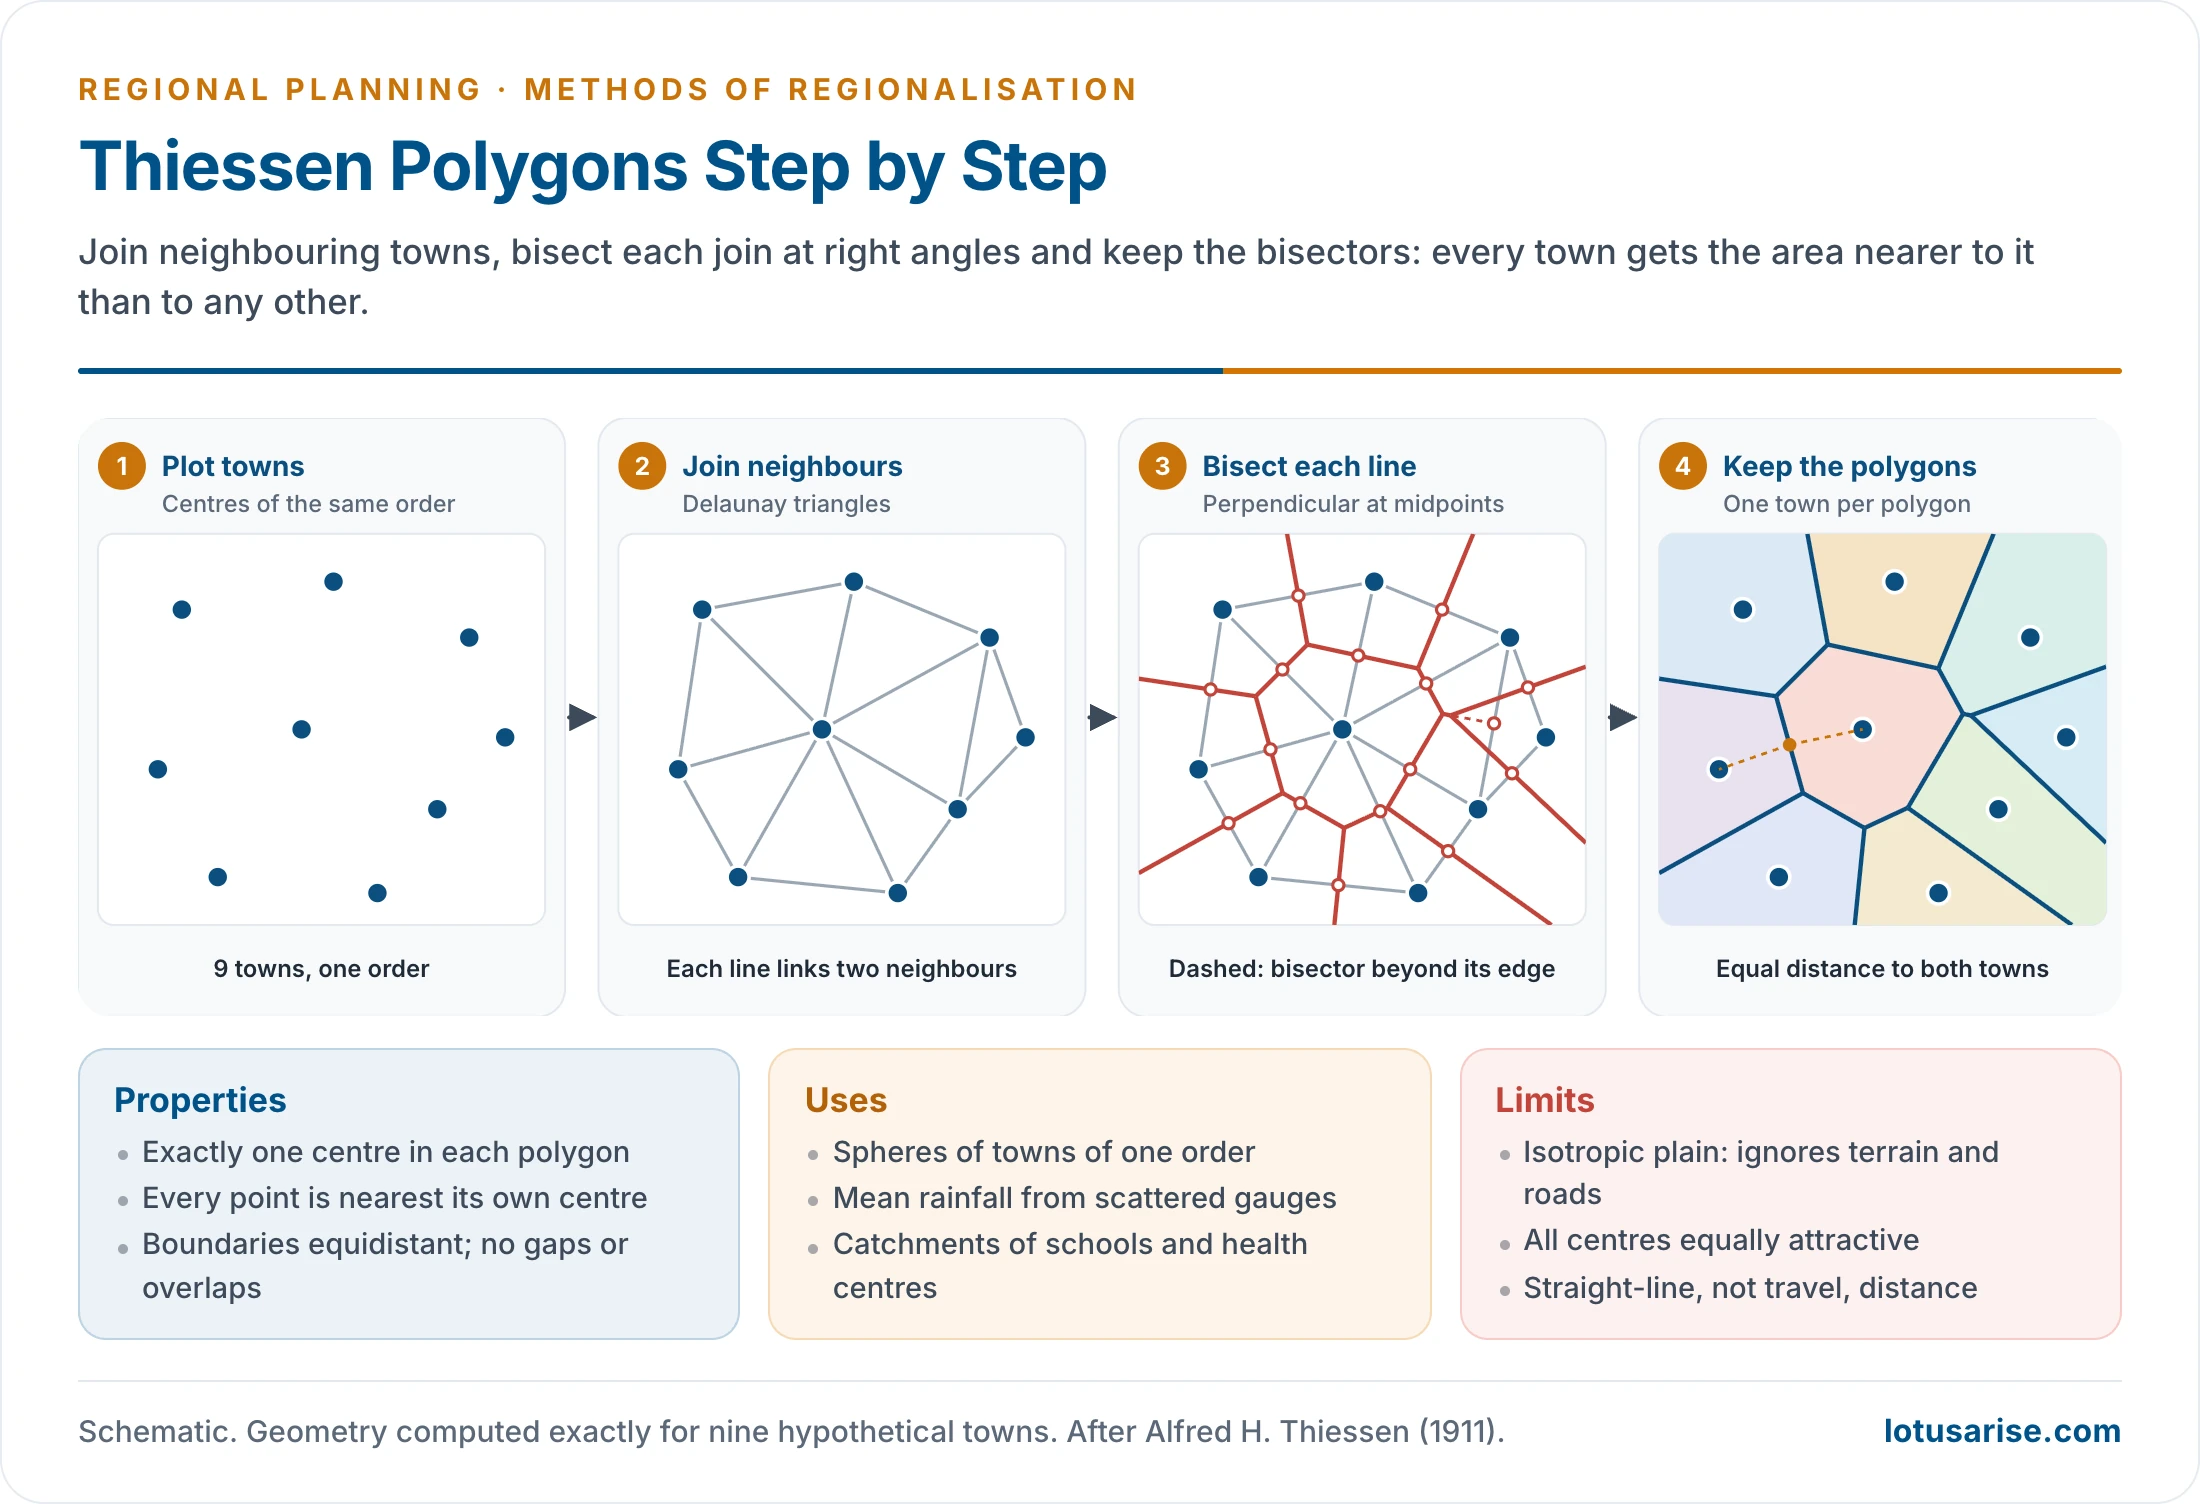
- A simple geometric method that assigns every point to its nearest centre. It was proposed by Alfred H. Thiessen (1911) to estimate average rainfall from scattered gauges; the same figures are known in mathematics as Voronoi or Dirichlet tessellations.
- In regional geography it marks the spheres of influence of urban nodes on an assumed isotropic plain.
- Construction:
- Plot all centres of the same order on the map; each will be the core of one polygon.
- Join neighbouring centres by straight lines to form triangles (Delaunay triangulation).
- Find the midpoint of each line.
- Draw the perpendicular bisector at each midpoint; the bisectors meet at the polygon vertices.
- Remove the triangle lines: the bisectors enclose polygons, one per centre.
- Properties:
- Each polygon contains one and only one centre.
- Every point inside is closer to its own centre than to any other.
- Each boundary is equidistant from the two centres it separates.
- The polygons cover the whole area without overlap.
| Application | Nodes | Example |
|---|---|---|
| Functional regions | Towns of one order | Donald J. Bogue’s 67 metropolitan territories of the USA (1949); market areas of district towns |
| Rainfall averaging | Rain gauges | Mean basin rainfall in hydrology |
| Service areas | Hospitals, schools, post offices | Catchments of primary health centres |
| Administration | Offices and police stations | Fair jurisdictions by distance, panchayat service planning |
- Limitations: it ignores terrain, rivers and roads; treats all centres as equally attractive; uses straight-line distance, not travel time or cost; gives rigid lines that rarely match real or administrative boundaries; and misses the historical and cultural factors behind real spheres of influence.
- Weighted (multiplicatively weighted) polygons shift each boundary towards the smaller centre, combining Thiessen geometry with the breaking-point logic.
Delimiting Naïve, Perceptual and Planning Regions
- Naïve regions, such as cultural, perceptual and backward regions, have no agreed boundary. Their elements are complex and contradictory, so only vague, transitional boundaries can be drawn. The methods are empirico-statistical.
- Threshold comparison: the Yi − Yj rule is applied to an indicator or composite index, unit by unit, to trace a backward region.
- Flow of cultural traits: the core of a cultural region is identified, and the spread of its traits (language, script, religion, dress, food, festivals, house types, arts) is traced outward.
- For Mithila, the core lies around Darbhanga and Madhubani in Bihar. As Maithili speech, Madhubani painting and marriage customs thin out towards the periphery, the transitional boundary is drawn.
- Buddhist cultural zones of the Himalaya merge gradually into neighbouring traditions, so no linear boundary is possible.
- Perception surveys and toponyms: mental maps drawn by residents and the frequency of regional names in place and business names (Wilbur Zelinsky’s method, 1980) map vernacular regions.
- Empirico-statistical planning regions: the NCR.
- The statistical component decided which districts to include on measurable criteria such as commuting and dependence on Delhi.
- The empirical component followed observed migration, urban sprawl and ribbon development along highways.
- The NCR therefore reaches outward along the main roads from Delhi rather than as a circle. Since the NCR Planning Board Act, 1985, it has grown to about 55,083 sq km, with Delhi and 14 districts of Haryana, 8 of Uttar Pradesh and 2 of Rajasthan.
- Administrative compromise: most planning regions are finally fitted to districts and blocks, because plans need data and machinery.
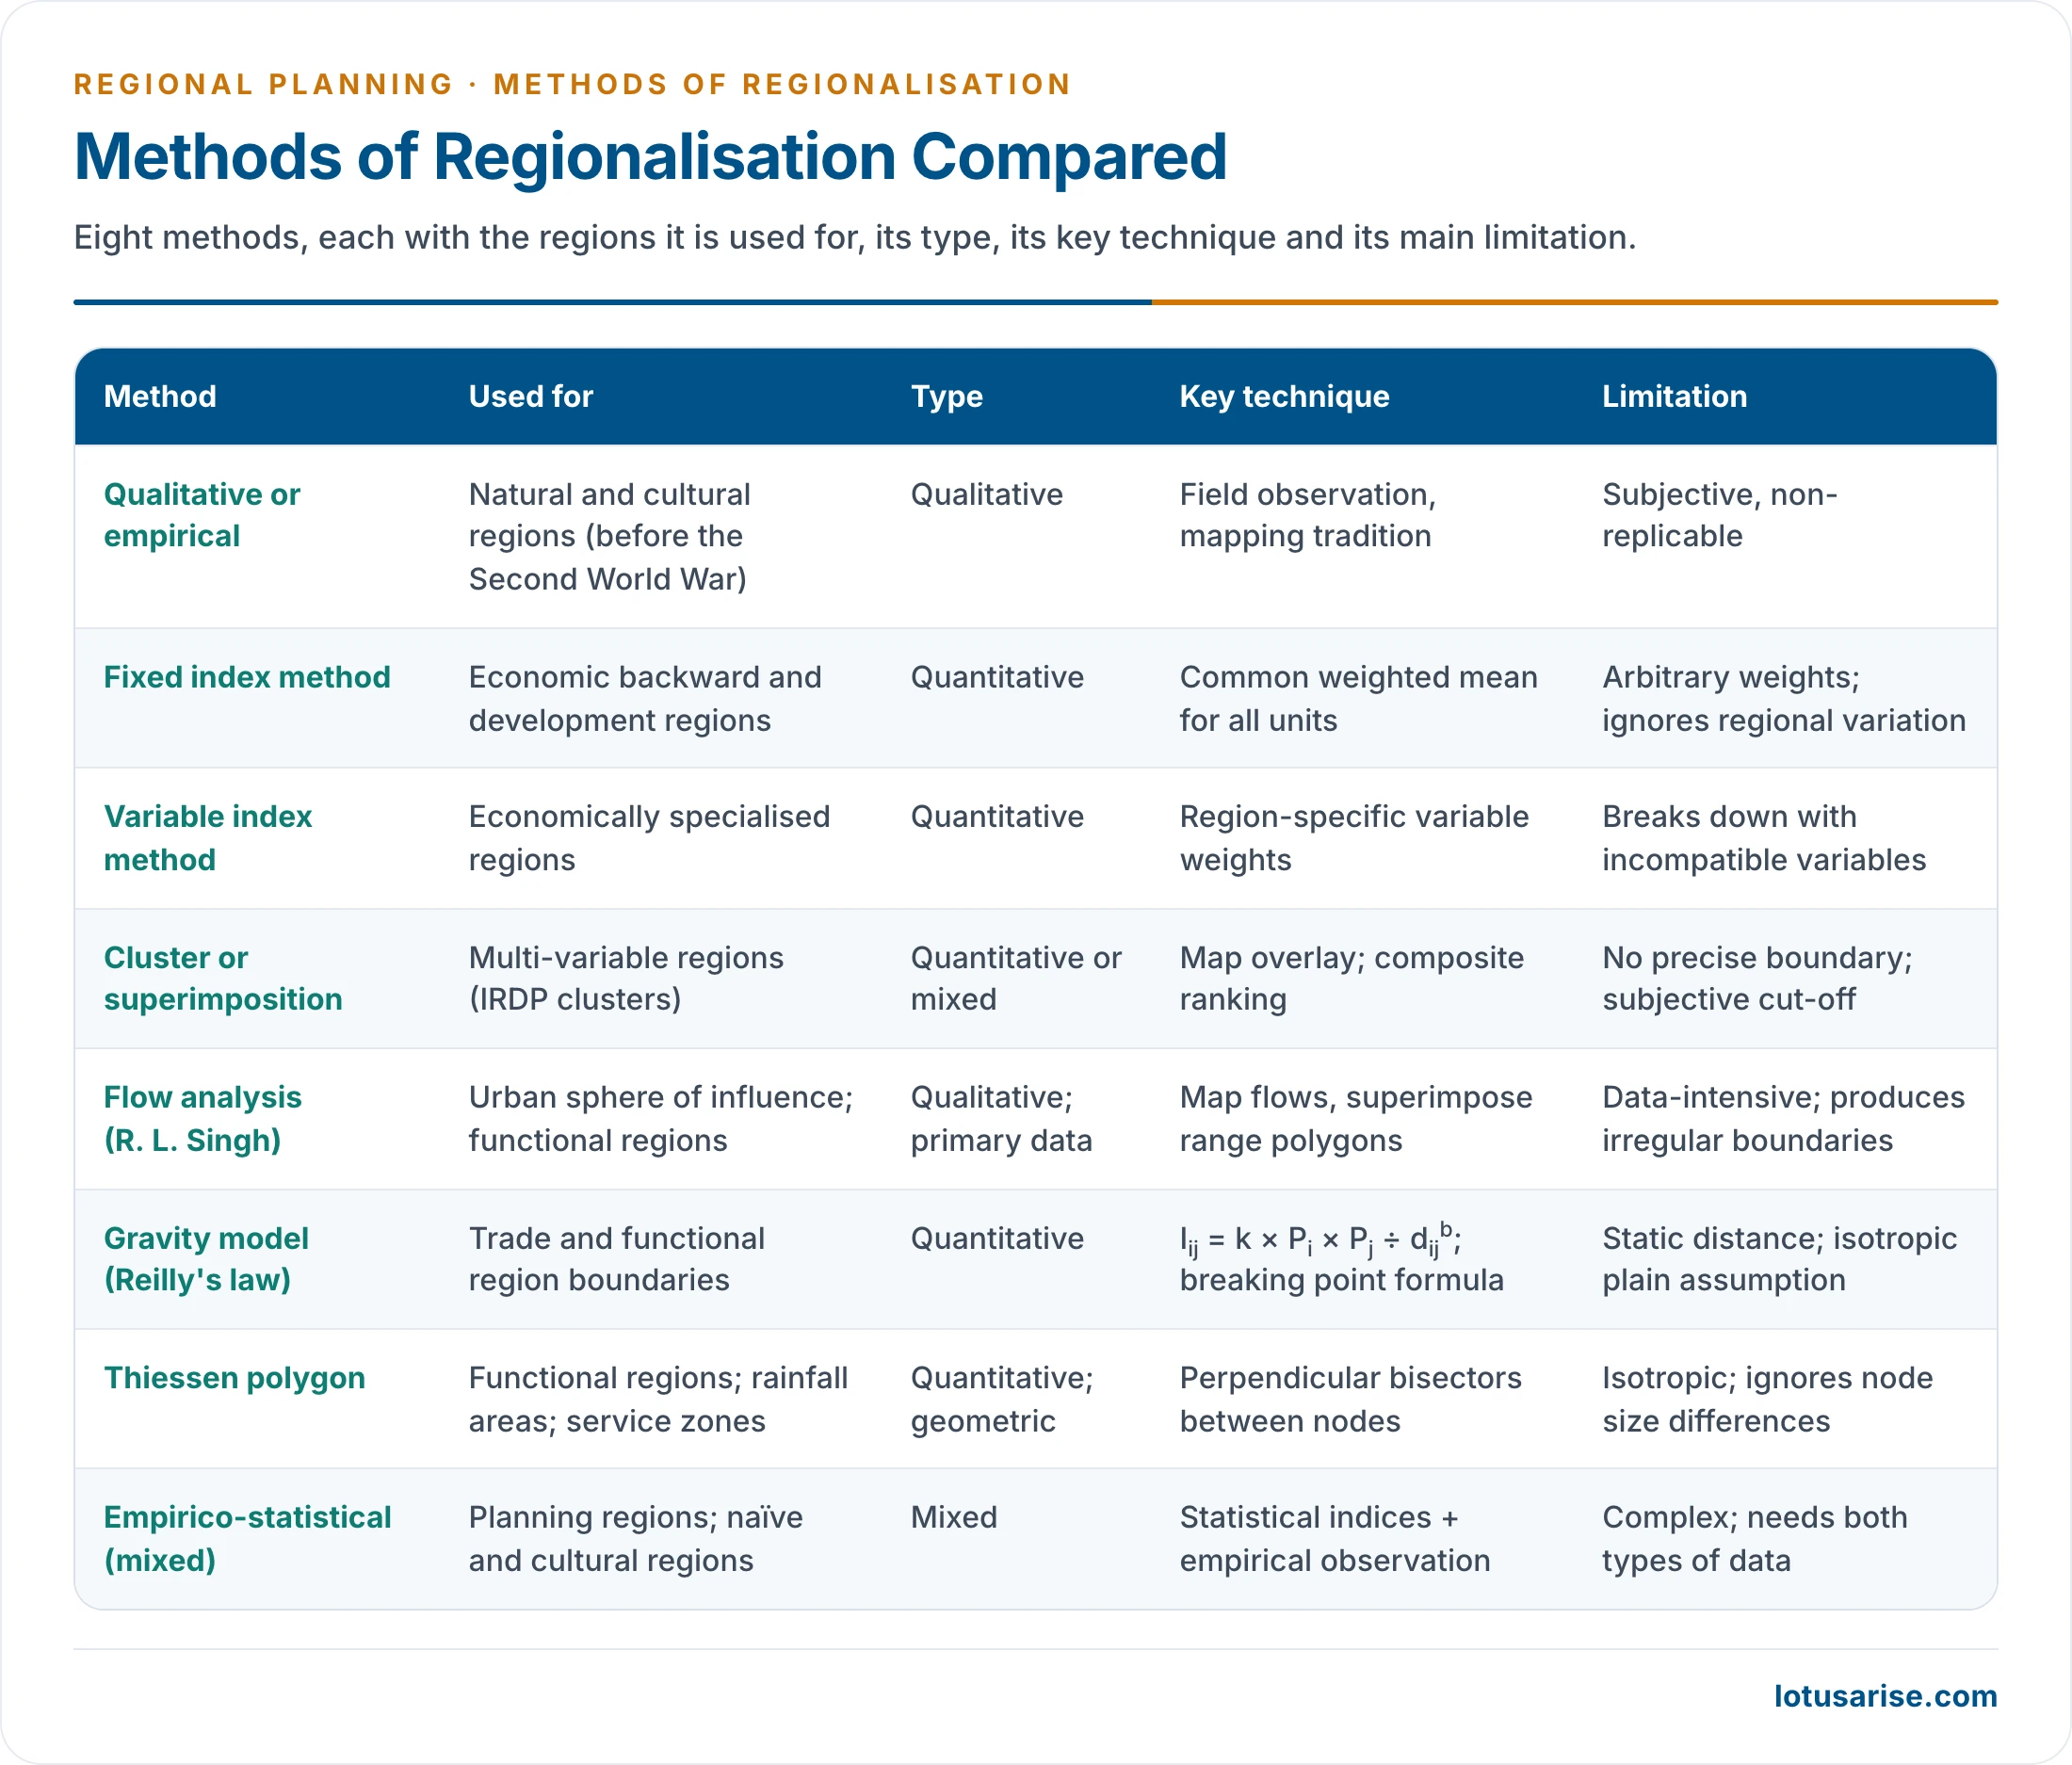
| Region type | Main method | Boundary character | Indian example |
|---|---|---|---|
| Formal (physical) | Isopleths, superimposition | Fairly precise where data are clear | Thar Desert and arid zone by isohyets, tundra by isotherm, physiographic regions |
| Formal (economic, social) | Fixed or variable index, composite ranking, clustering | Threshold-based classes | Rajan Committee State classes, Backward Regions Grant Fund districts, drought-prone districts |
| Functional (nodal) | Flow analysis, gravity model, graph theory, Thiessen polygons | Gradient fading with distance | Delhi NCR, Mumbai Metropolitan Region, Banaras umland |
| Naïve or cultural | Empirico-statistical, trait mapping, perception surveys | Transitional zone, never a line | Mithila, Avadh, Bundelkhand |
| Planning | Administrative units plus composite criteria | Administrative lines used pragmatically | KBK, tribal sub-plan areas, NCR |
Choosing a Method
- Start from the purpose and the type of region: similarity calls for thresholds, indices or clustering; dependence on a centre calls for flows or gravity models; identity calls for trait mapping and perception surveys.
- Match the method to the data: field surveys suit a single city region; census tables suit composite indices over districts; flow matrices suit graph theory and factor analysis.
- Combine and cross-check: a statistical boundary is tested against observed behaviour, and a judgement boundary against the numbers. Most robust regions come from more than one method.
- Keep the unit in view: the same method on blocks and on districts can give different regions, so the base unit should match the scale of the plan.
Problems and Indian Practice
Problems in Delimitation
- Lack of correlation: regions defined by different criteria seldom coincide; formal and functional boundaries rarely match.
- Dynamic regions: flows, incomes and land use change, so boundaries date quickly.
- Choice and weighting of criteria is subjective, and different weights give different regions.
- Modifiable areal unit problem: results change with the size and shape of base units, as Stan Openshaw (1984) showed. District averages can hide poor blocks.
- Ecological fallacy: a region’s average need not describe its people.
- Data gaps: many indicators exist only for districts and only for census years; in the gravity model, masses and distances are hard to measure.
- Edge effects and transitional zones: a line is drawn across what is really a gradient.
- Political pressure: inclusion can bring funds or status, so boundaries are bargained over.
Regionalisation in India
- Major attempts at regionalising India:
| Scholar or body | Criteria | Regions | Method |
|---|---|---|---|
| National Atlas Organisation | Physiography: landforms, geology, soils | 5 macro, 12 meso | Superimposed physical maps |
| V. Nath | Soil, climate, topography, land use | 15 resource development regions | Composite of several criteria |
| Planning Commission | Agro-climate, fitted to administrative units | 15 agro-climatic regions | Superimposition |
| National Sample Survey | Economic and geographic homogeneity | 58 meso regions in older counts | Composite criteria |
| Rajan Committee (2013) | Composite development index | 28 States in 3 classes | Fixed index |
| NITI Aayog (2018) | 49 indicators in 5 themes | 112 aspirational districts | Fixed index, delta ranking |
- India’s schemes of planning regions, from the macro, meso and micro resource and economic regions of the 1960s to the Planning Commission’s 15 agro-climatic regions (1989), rest on these techniques: superimposed physical maps for natural regions, composite criteria for agro-climatic and economic regions.
- Composite indices now decide where money goes: the Rajan Committee’s State index (2013), the 272 Backward Regions Grant Fund districts (2007–2015; the Rajan Committee ranked States, not these districts), selected on parameters such as income, literacy, infant mortality and road length, and NITI Aayog’s 112 aspirational districts (2018) tracked on 49 indicators in five themes.
- Functional regions are drawn for metropolitan planning (NCR, Mumbai and Bengaluru metropolitan regions), and agricultural regionalisation uses crop combination and intensity indices of the same family.
- Physiographic regionalisation superimposes geological, relief, soil and drainage maps to give six formal regions: Himalaya, Great Plains, Peninsular Plateau, Thar Desert, Coastal Plains and Islands.
- Human development regionalisation uses a fixed composite of income, education and health. On earlier scores:
- High: Keralam (Kerala), Delhi, Goa, Himachal Pradesh, Punjab.
- Medium: Maharashtra, Karnataka, Tamil Nadu, Andhra Pradesh, Gujarat.
- Low: Bihar, Uttar Pradesh, Madhya Pradesh, Chhattisgarh, Jharkhand, Odisha.
- Scholars have divided India into 11 to 20 macro regions on agro-climatic or resource criteria. Beyond the five Zonal Councils there is no formal macro-regionalisation; such groups cooperate on inter-State matters such as river water and power grids.
Previous Year Questions
2021Suggest criteria, indicators, and techniques for delimitation of formal regions.2016What is a ‘region’? Describe ‘Thiessen’ polygon method of regional delimitation.2005What is a region? Discuss the methods of regionalization.2000What is a region? Discuss the types of regions & the methods of regionalization.





Lucky to have such a quality notes.
Sir/ma’am…plzz share the sources from where u have prepared these notes.. because I’m preparing for optional from ur site only
Main reference: https://lotusarise.com/geography-optional-books-for-upsc/ and Internet.
can you please share the reference for regional geography.
No doubt the notes are covered very precisely acc to syllabus, but notes cannot justify the questions demand…..considering pyqs I am not able to find the topic, like “Thiessen Polygon”….nowhere mentioned.
I have purchased the notes, but difficult for me to collaborate things.
Can be found under theories of urban influence…
Having these notes means no need to buy any book further
Good,thanks
I am a faculty and when i see a topic on lotusrise, then i am assured that not much of additional material is needed. almost everything is sorted.
Thank you so much for your kind words! Hearing this from a faculty member truly validates our effort to deliver complete and reliable study material. We’re delighted to know LotusArise helps make your teaching and research easier!